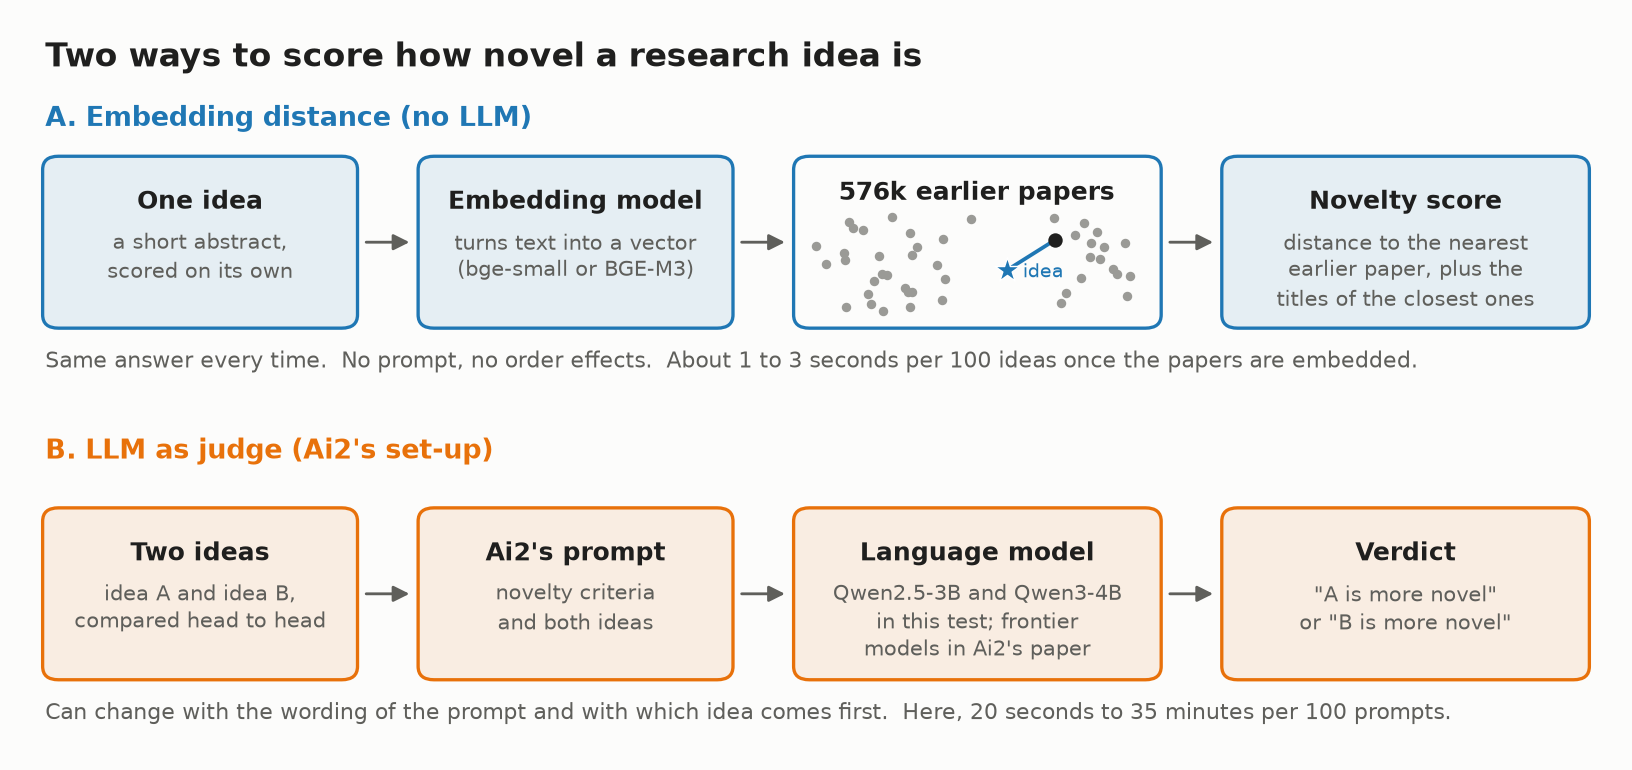
Judging research novelty cheaply: comparing Ai2’s benchmarks to an embedding distance metric, and a small QWEN-model (with and without reasoning).
evaluation
embeddings
llm-as-judge
research
benchmarks
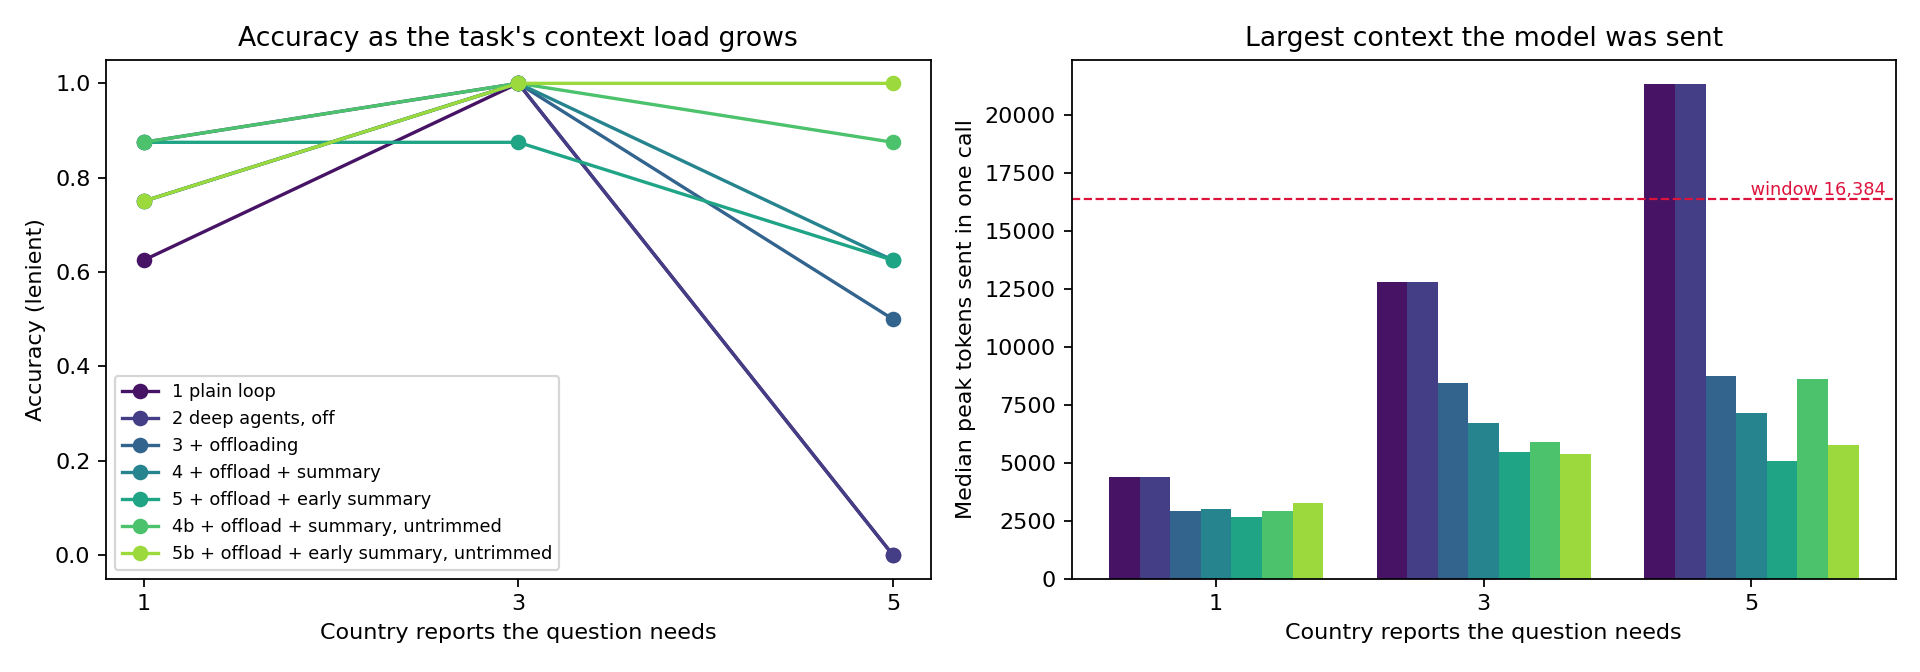
Context rot in a small local agent: offloading works, summarisation fails silently
agents
context engineering
deep agents
langchain
local models
evaluation
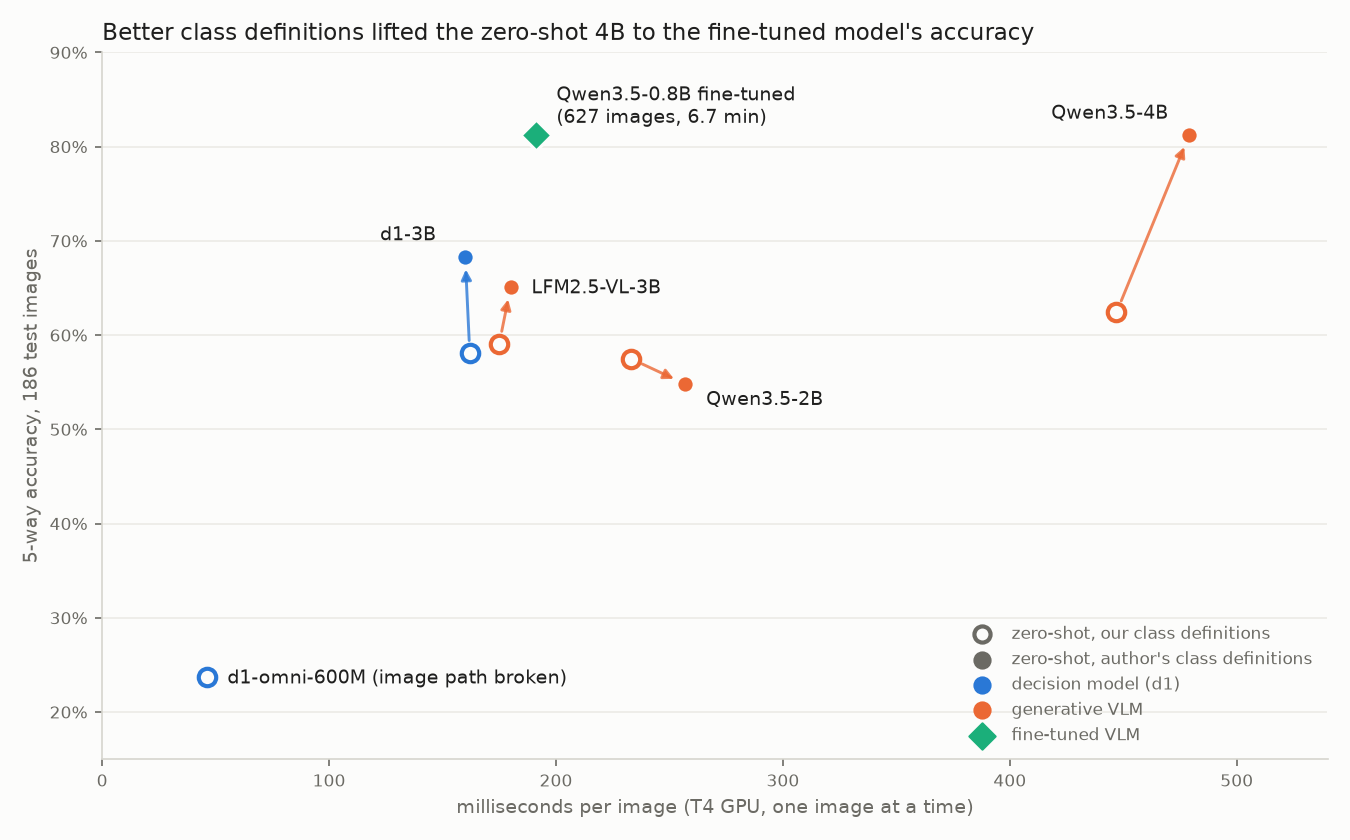
Spotting warehouse hazards: the prompt mattered as much as fine-tuning
decision models
vision-language models
fine-tuning
unsloth
evaluation
prompting
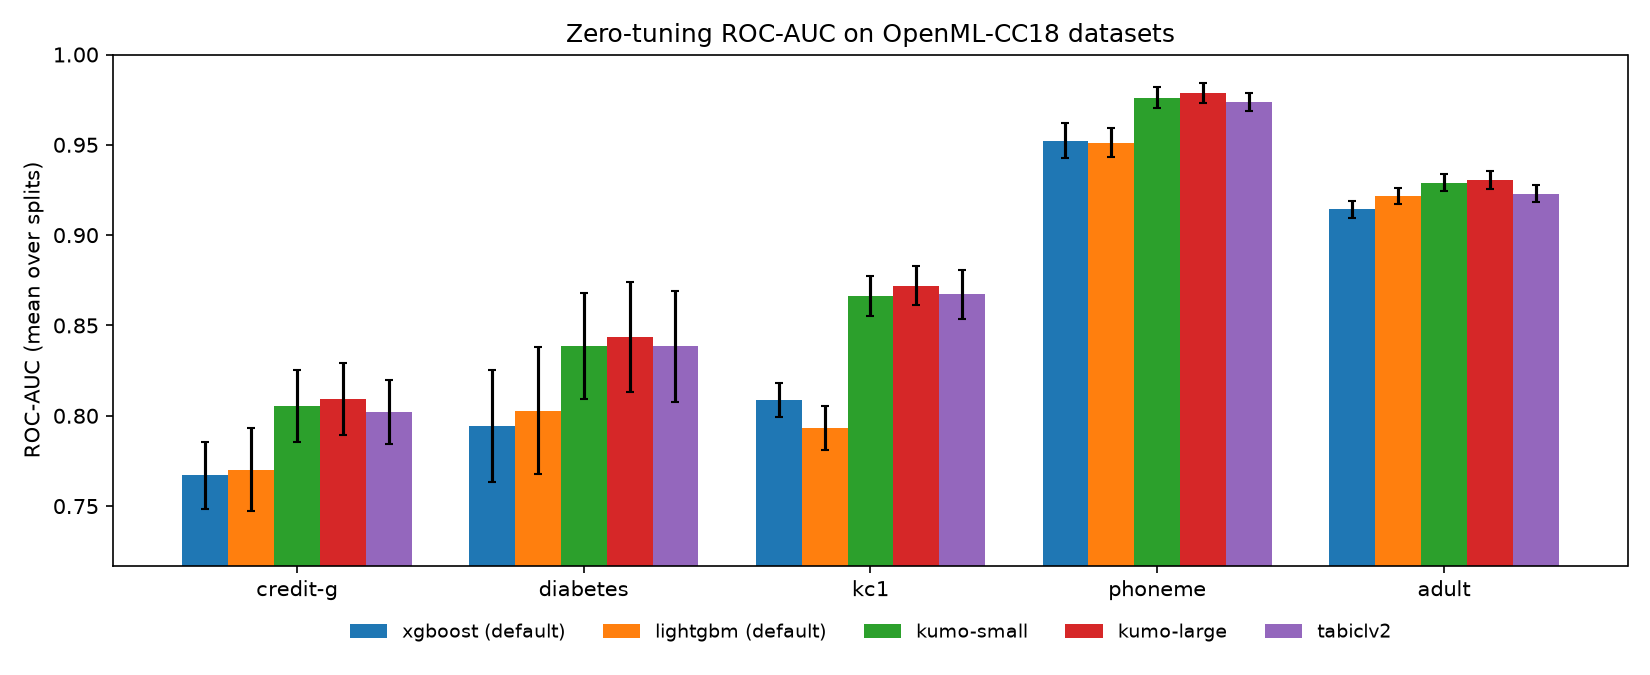
Can a pretrained model beat XGBoost without training?
tabular
foundation models
in-context learning
xgboost
benchmarking
No matching items